Comparative evaluation of three semantic segmentation architectures for severity assessment of Hemileia vastatrix and Mycena citricolor on Coffea arabica var. Esperanza L4A5.
Three deep-learning segmentation models, the compact DeepLabV3+ and UNet++ (MobileNetV2 encoders) and the SegFormer-B5 transformer, compared for measuring the severity of coffee leaf rust (Hemileia vastatrix) and American leaf spot, or ojo de gallo (Mycena citricolor), on 684 scanned leaves of Coffea arabica var. Esperanza L4A5.
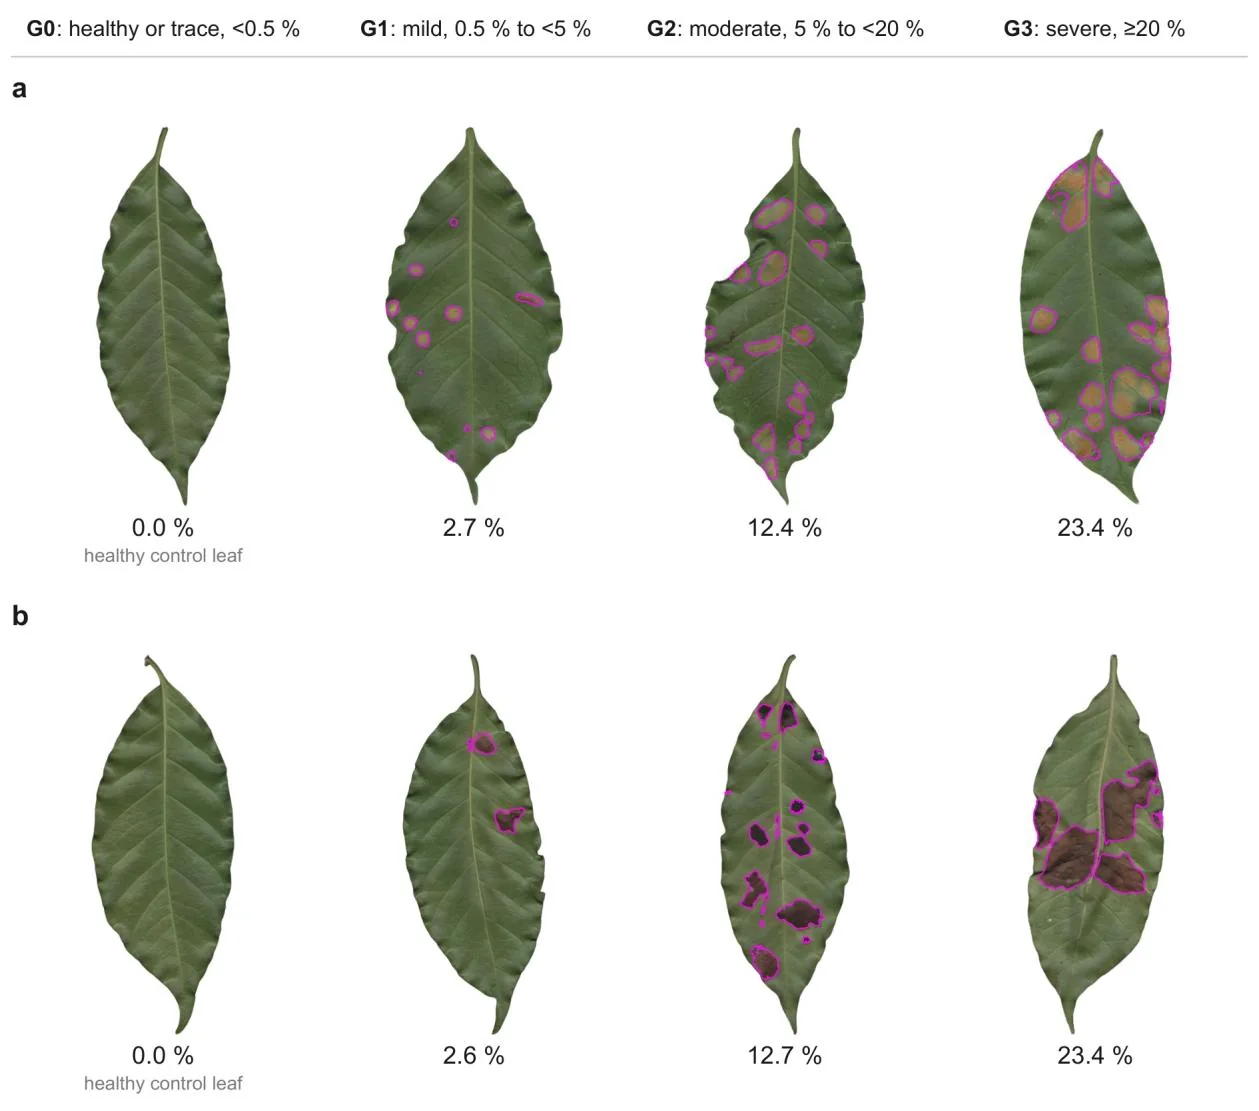
Each model segments lesions pixel by pixel, converts the lesioned area into a severity percentage, and maps it to a four-level grade (G0 to G3). One model was trained per disease, in the environment where it occurs: ojo de gallo at EARTH University in Guácimo (35 m) and rust on a farm in Sarchí (1,248 m). Rust cut regional coffee production by 16 to 31 % during the 2008–2013 crisis in Central America and Colombia (Avelino et al., 2015); this work offers an objective, reproducible alternative to grading severity by eye. Code, models and a demonstration dataset are public (Zenodo DOI 10.5281/zenodo.22701350).
-
01
Leaf Scanning
684 leaves · 1,367 images · Epson V39 II flatbed scanner, both leaf faces at 23.6 px/mm · flat-field correction and white balance.
-
02
Annotation
ojo de gallo masks corrected by hand in CVAT · rust masks semi-automatic (colour detector refined with SAM 2, spot-checked) · grades G0–G3 from the masks · leaf-level splits audited to zero leakage.
-
03
Model Training
DeepLabV3+ and UNet++ with MobileNetV2 encoders (17 and 27 MB) against the SegFormer-B5 transformer (340 MB) · one model per disease · all three retrained under one matched protocol with three random seeds.
-
04
Evaluation
Sealed test set · leaf-level IoU, severity MAE and Bland–Altman, quadratic-weighted kappa · Wilcoxon tests with Holm correction · colour-threshold baseline · blinded panel of five experts.
-
05
Deployment
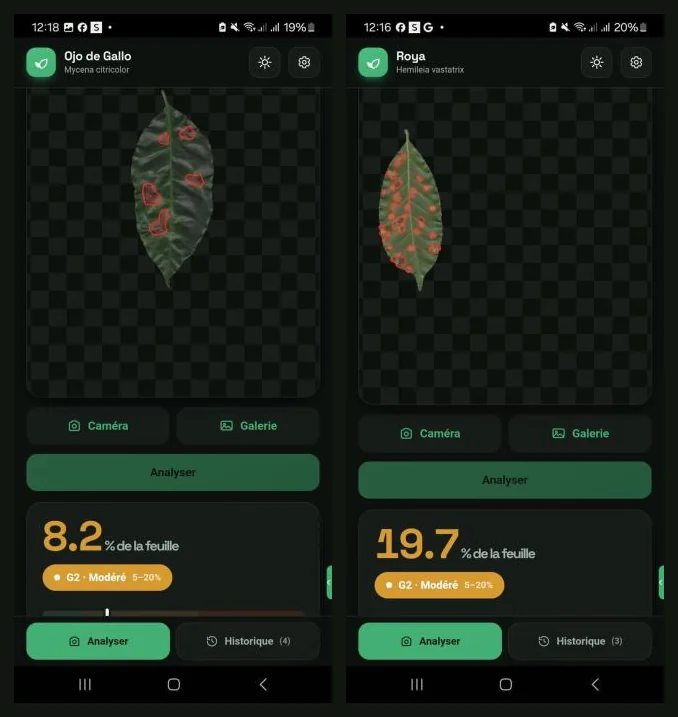
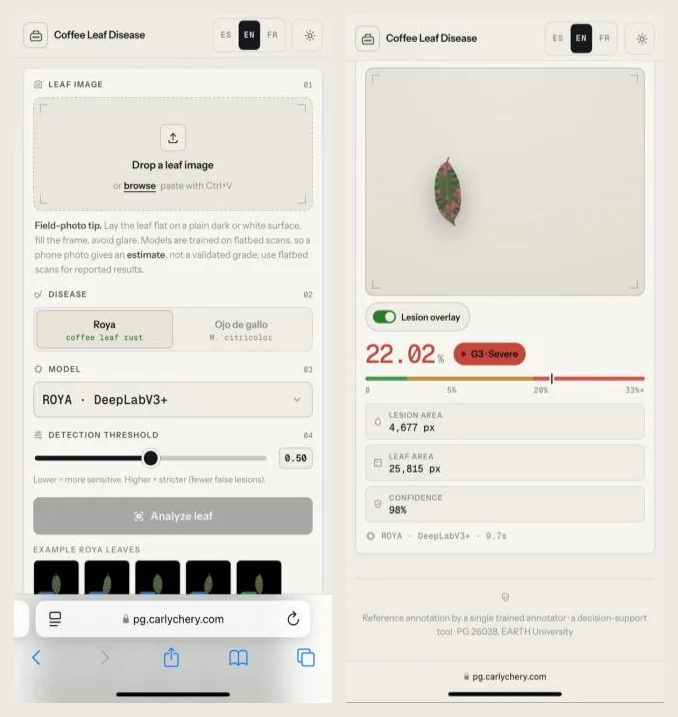
Two tiers: an offline mobile app for Android and iOS runs DeepLabV3+ and UNet++ on the phone with ONNX Runtime; a trilingual web app at pg.carlychery.com serves all three models, SegFormer-B5 among them.
All figures are out-of-sample, on a test set sealed before final training (55 ojo de gallo and 21 rust leaves). Trained once each, SegFormer-B5 had the highest lesion overlap (leaf IoU 0.884 for ojo de gallo, 0.767 for rust). Retrained under one matched protocol with three seeds, that ranking largely dissolved.
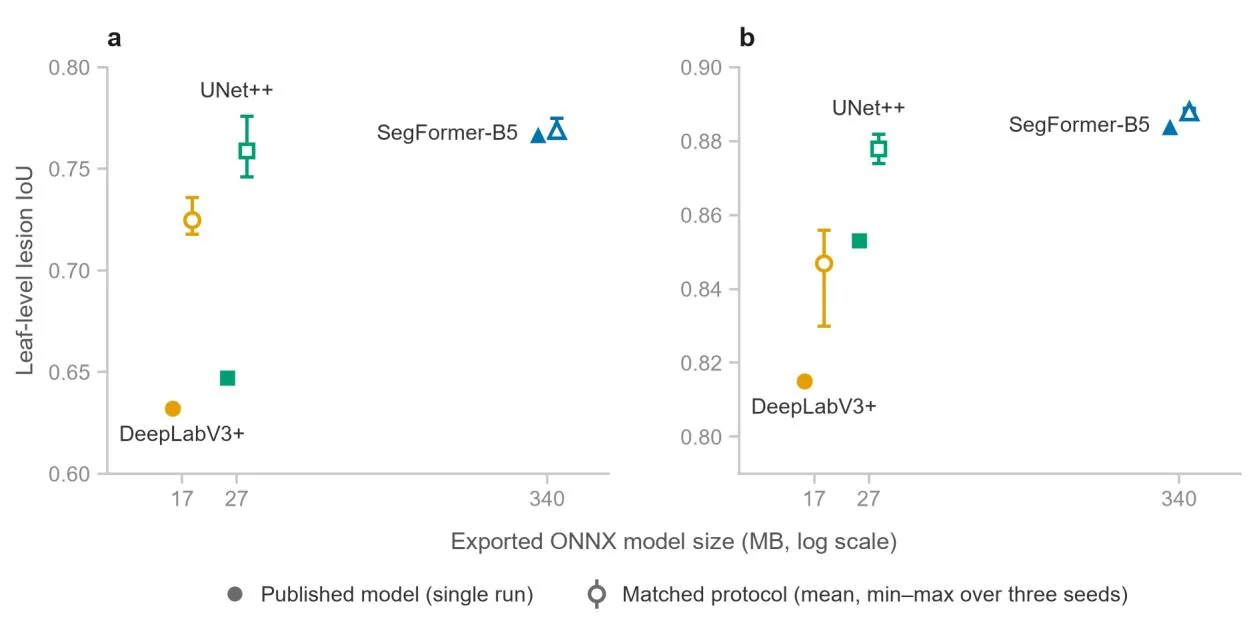
The three architectures on the sealed test set. The compact models are one twelfth (UNet++, 27 MB) to one twentieth (DeepLabV3+, 17 MB) of the transformer's 340 MB, which is why only they run on the phone.
| Model | Size | IoU rust |
IoU ojo de gallo |
QWK rust |
QWK ojo de gallo |
On-device |
|---|---|---|---|---|---|---|
| SegFormer-B5 (MiT-B5) | 340 MB | 0.769 ± 0.005 | 0.888 ± 0.001 | 0.88 | 0.95 | Web app |
| UNet++ (MobileNetV2) | 27 MB | 0.759 ± 0.015 | 0.878 ± 0.004 | 0.79 | 0.98 | Yes |
| DeepLabV3+ (MobileNetV2) | 17 MB | 0.725 ± 0.010 | 0.847 ± 0.015 | 0.88 | 0.97 | Yes |
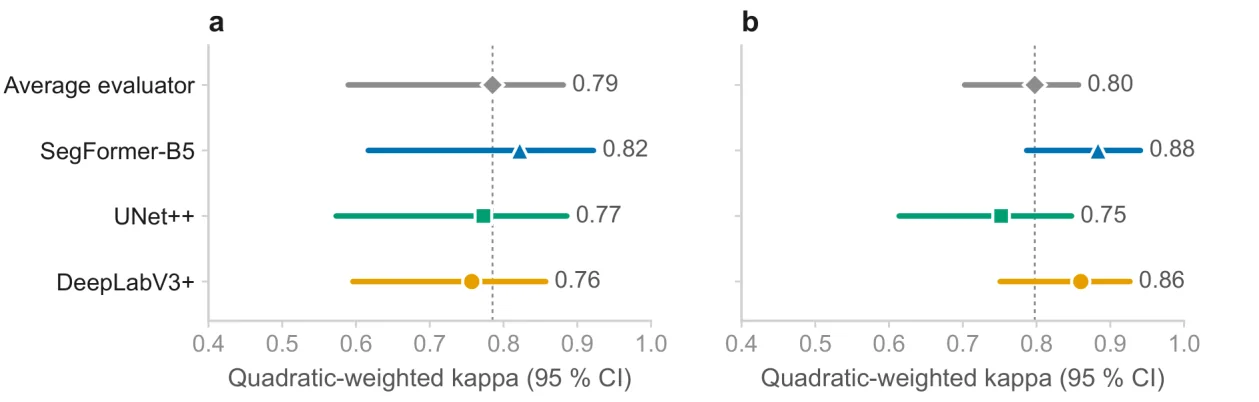
IoU: leaf-level lesion IoU under the matched training protocol, mean ± SD over three seeds. QWK: quadratic-weighted kappa of the original models' grades against the mask-derived reference (rust: a semi-automatic reference). Test set: 21 rust and 55 ojo de gallo leaves.
- The ranking was mostly training budget. Trained once each, SegFormer-B5 led clearly. Under one matched protocol with three seeds, UNet++ came level on rust (leaf IoU 0.759 vs 0.769) and within about 0.01 on ojo de gallo (0.878 vs 0.888), at one twelfth of the size.
- Severity close to the reference. Predicted severity fell within 0.15 to 0.25 % of the reference for ojo de gallo and 0.99 to 1.77 % for rust (Pearson r ≥ 0.95), and grade errors stayed between adjacent grades. Against a blinded five-expert panel, SegFormer-B5 agreed more closely than the average expert for ojo de gallo, though not for rust.
- No disease invented on healthy leaves. A tuned colour threshold flagged 12 of 21 healthy leaves as rust; the networks flagged none. The rust overestimation was an operating-point effect: a calibrated threshold, or a symmetric loss, cut the SegFormer-B5 bias from +0.99 % to about +0.12 %.
A decision-support research tool, not a validated diagnosis. Results are on flatbed scans; phone photos still need an external validation before any field-use claim. Rust masks are semi-automatic, and all healthy leaves came from the ojo de gallo site, so rust specificity is confounded with site.
Test the thesis models on a coffee leaf
Upload a coffee-leaf image at pg.carlychery.com, choose the disease and the model, and the web app returns the lesion overlay, the severity percentage and a G0–G3 grade. It serves all three thesis models, SegFormer-B5 among them, for coffee leaf rust and ojo de gallo.